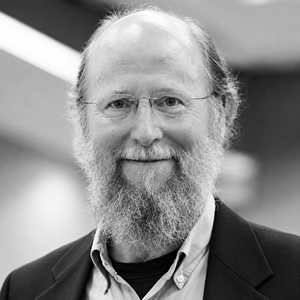
Richard S. Sutton is a Canadian-American computer scientist, researcher, and professor at the University of Alberta. He is regarded as a key pioneer of reinforcement learning, having developed many of its core mathematical algorithms.
Temporal Difference and Policy Gradients
Sutton earned his Bachelor's in Psychology from Oakland University and his Ph.D. in Computer Science from UMass Amherst in 1984 under Andrew Barto. His doctoral research introduced temporal difference (TD) learning, which allows agents to update their predictions about future rewards step-by-step rather than waiting for a final outcome. He also co-developed **policy gradient methods**, which directly optimize policy parameters and form the basis of algorithms like PPO (used to align ChatGPT via RLHF).
DeepMind and Keen Technologies
Sutton served as a Distinguished Research Scientist at Google DeepMind and recently joined John Carmack's AGI startup, Keen Technologies, to work on the conceptual foundations of artificial general intelligence.